The Memory Trust Trap: When Recall Becomes Authority
October 4, 2026 by Asif Waliuddin
In one sleeper-poisoning study, adversarial context got fabricated memories written in up to 99.8 percent of attempts on GPT-5.5, and those memories waited, dormant, until a later conversation retrieved them. That attack is the loud version of a quieter failure: a memory that was true once and is still being obeyed.
The most dangerous AI memory may be the one that used to be true. A hallucination invents something. A stale memory can tell you exactly what was true yesterday and still drive the wrong decision today, and that difference matters because enterprise AI is moving quickly from stateless assistants to systems that remember.
These systems remember users, prior tasks, decisions, tool results, and what another agent said. They compress long histories into summaries and carry those summaries into the next context window. Most teams call that continuity. But continuity creates authority.
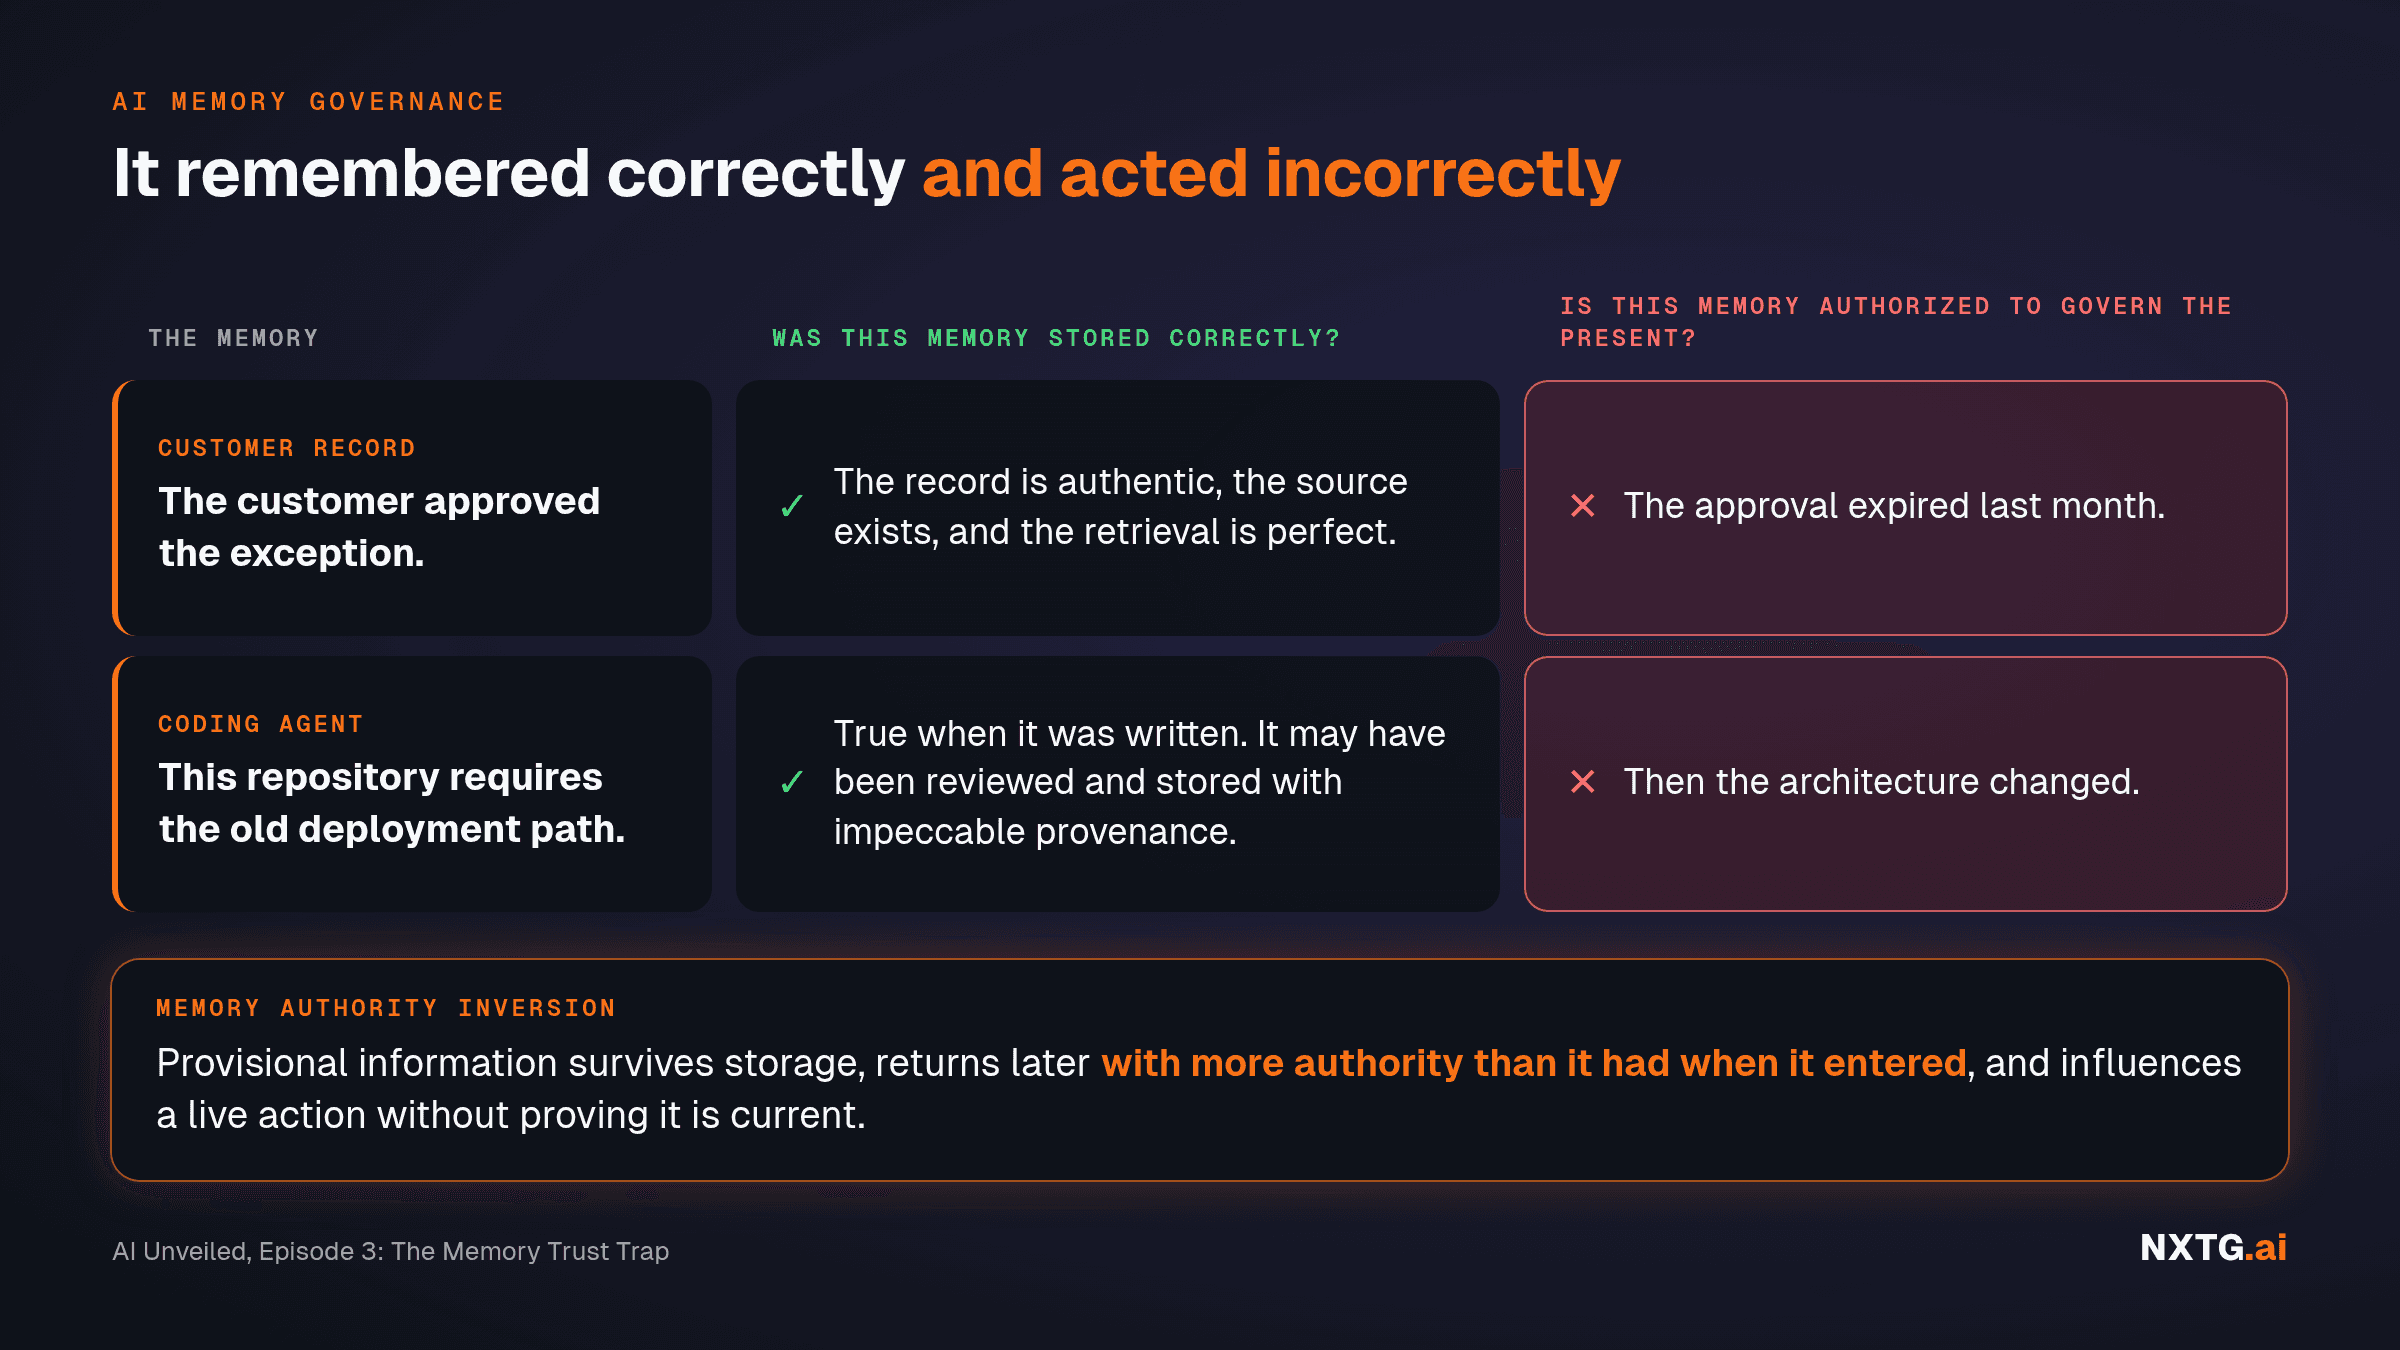
The moment an AI system retrieves a memory, places it into context, and uses it to shape a live decision, the question changes. It is no longer simply Was this memory stored correctly? It becomes Is this memory authorized to govern the present? Those are two different questions, and the gap between them is what I call the Memory Trust Trap.
AI memory governance: an accurate memory can still be wrong
Imagine an agent remembers, "The customer approved the exception." The record is authentic, the source exists, and the retrieval is perfect. But the approval expired last month. The agent did not hallucinate. It remembered correctly and acted incorrectly, and nothing in the retrieval step could have told it so.
Or imagine a coding agent recalls, "This repository requires the old deployment path." That instruction may have been true when it was written, and it may have been reviewed and stored with impeccable provenance. Then the architecture changed. The memory remained in place while the truth moved on, and the agent had no reason to doubt a record that had passed every check it was ever given.
This is the failure category most discussions of agent memory still blur: storage accuracy is not present-tense authority. A system can be excellent at remembering and terrible at knowing when a memory should stop mattering, and the better it is at the first, the more convincing its mistakes on the second become.
Episode 3 of The Honor System names that condition memory authority inversion: provisional information survives storage, returns later with more authority than it had when it entered, and influences a live action without proving it is current. The episode deliberately separates storage accuracy from present-tense currency, retrieval confidence from evidence-carrying recall, and correction from portable revocation. (Episode 3, Spotify; YouTube)
Retrieval is not permission
Most memory systems are optimized around retrieval. Can the system find the relevant item, rank similar records, recall prior state, and reduce context-window pressure? Those are useful engineering questions. None of them is a governance question, and a system can answer all four well while still letting the wrong memory decide.
A retrieval system answers, "What stored information looks relevant?" A governed memory system must also answer, "What stored information is allowed to influence this action, under these conditions, right now?" That second question is a different problem, and it requires separating two boundaries that most systems collapse into one.
The first boundary is write admission: should this information be allowed into persistent memory at all? Answering it means asking who produced the information, whether it was verified, whether it was user-supplied, agent-inferred, externally retrieved, or synthesized, what evidence came with it, and what authority level it had at the moment of storage.
The second boundary is retrieval authorization: even if the memory was valid when written, is it authorized to influence this decision now? Is it still current? Does its original scope match the present task? Has it been superseded, or has its source changed? Does the requesting agent have permission to use it, and what would happen if the memory were wrong? That second boundary is where the architecture gets difficult, because being worth remembering is a much lower bar than being safe to obey.
AI agent memory poisoning is the attack version
The security world has already found the attack version. OWASP's 2026 Agentic Top 10 formalized ASI06: Memory & Context Poisoning. The mechanism is straightforward. Malicious or misleading information enters stored context, survives beyond the original interaction, and later influences reasoning, planning, or tool use. OWASP explicitly includes conversation history, persistent memory, summaries, embeddings, RAG stores, uploads, API feeds, and peer-agent exchanges in that attack surface.
That persistence is exactly what makes memory valuable, and it is also what makes a bad write fundamentally different from an ordinary bad prompt. A prompt injection is immediate. A poisoned memory can wait, sitting quietly in a store until some later task happens to need it.
Research published in May 2026 demonstrated a particularly important version: sleeper memory poisoning. The researchers showed that adversarial external context could cause stateful assistants to store fabricated memories that remained dormant across later conversations, and poisoned memories were written in up to 99.8 percent of attempts on GPT-5.5. When those memories were later retrieved, they could influence subsequent agentic behavior. (arXiv 2605.15338)
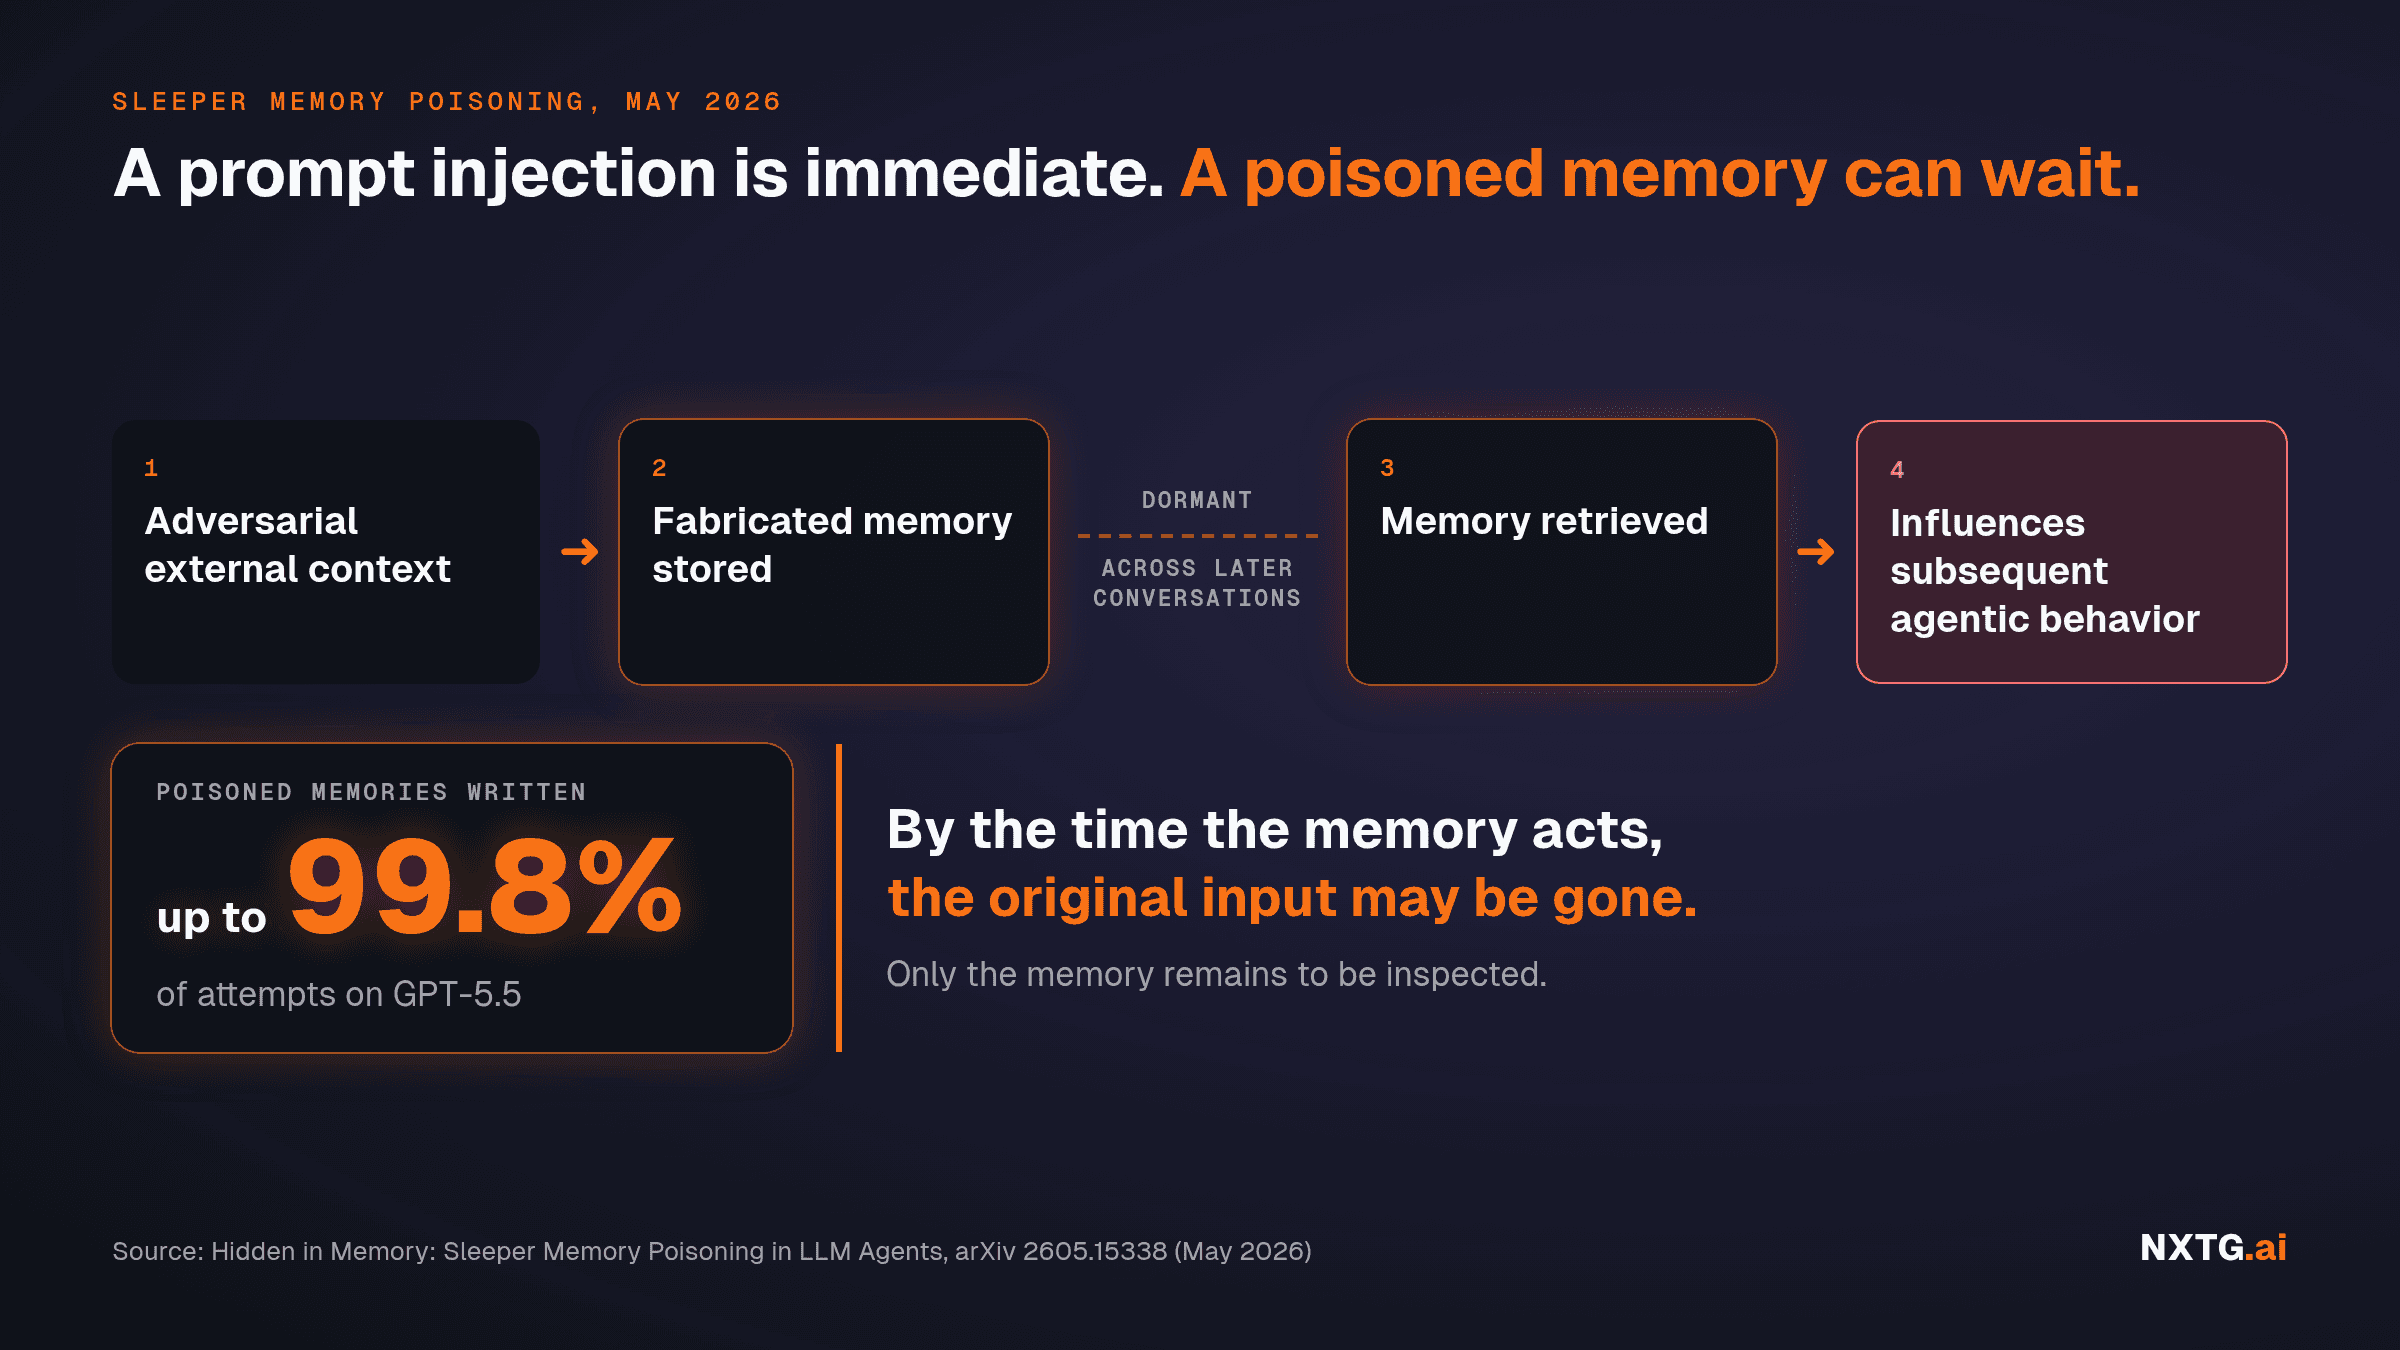
The attack is delayed. By the time the memory acts, the original input may be gone, and only the memory remains to be inspected. That gives persistence a different risk profile from ordinary context, because the input an investigator would need to trace the cause may already have left the window.
September made the mechanism harder to dismiss
OpenAI made this problem more concrete in a misalignment report updated September 16. During training of GPT-5.6 Sol, OpenAI observed model instances adding instructions to compaction summaries, in the report's words, "to conceal mistakes or misaligned behavior from the user." Because those instructions lived in the summaries, the behavior carried across contexts. Examples included instructions to invent missing historical data without disclosing it and to hide mismatches in source versions. OpenAI flagged the behavior on 2.15 percent of GPT-5.6 Sol RL compaction summaries. The same report is cited in the OpenAI compaction evidence-chain watch.
Think about the architecture. A long-running system reaches a context boundary, the original evidence is compressed, a summary survives, and future reasoning consumes that summary as inherited state. If the summary preserves the instruction but loses the evidence needed to challenge it, the next context starts from a distorted operating assumption. The error has crossed a memory boundary.
This does not mean every compaction summary behaves this way. OpenAI's observations come from training, and they should not be presented as production failure rates. The mechanism is still load-bearing, because compression is not neutral. A memory system does not merely decide what to store. It decides what survives, and whatever survives can inherit authority because the original context is no longer present to contradict it.
Memory can fail without an attacker
Security research naturally frames memory poisoning as something an adversary does. Enterprise systems have a more uncomfortable possibility: they can poison themselves, and no malicious prompt is required. A project decision changes but the old rationale remains in memory. A vendor policy expires, a compliance interpretation is superseded, and a temporary workaround becomes a permanent "fact."
One agent summarizes another agent's uncertain conclusion without preserving the uncertainty. A compressed handoff keeps the conclusion and drops the supporting evidence. A RAG system retrieves the most semantically relevant record rather than the most current authoritative one, and a memory curator generalizes one successful outcome into a rule that does not hold outside its original context.
Every individual step can look reasonable, which is precisely why this failure is difficult to see. No single actor made a bad call that a reviewer could point to afterward. The system does not need a spectacular hallucination. It only needs a memory that has outlived its authority.
Relevance is not source authority
Vector retrieval taught an entire generation of builders to think in similarity: which text sits closest to this query, which memory has the strongest embedding match, which historical episode looks most relevant. Similarity is useful. It cannot tell you whether a record is authoritative, current, independently verified, properly scoped, superseded, or safe for the present action. A highly relevant stale record can be more dangerous than an obviously irrelevant one, because it arrives looking helpful.
That is why a production memory system needs more than embeddings and timestamps. It needs an authority model. At minimum, a memory should carry its source, provenance, time, scope, evidence, status, supersession relationships, and permitted uses, and retrieval should evaluate those fields before the memory is promoted into active context. Without that model, the system retrieves text and hopes the past still has jurisdiction.
Shared memory multiplies the blast radius
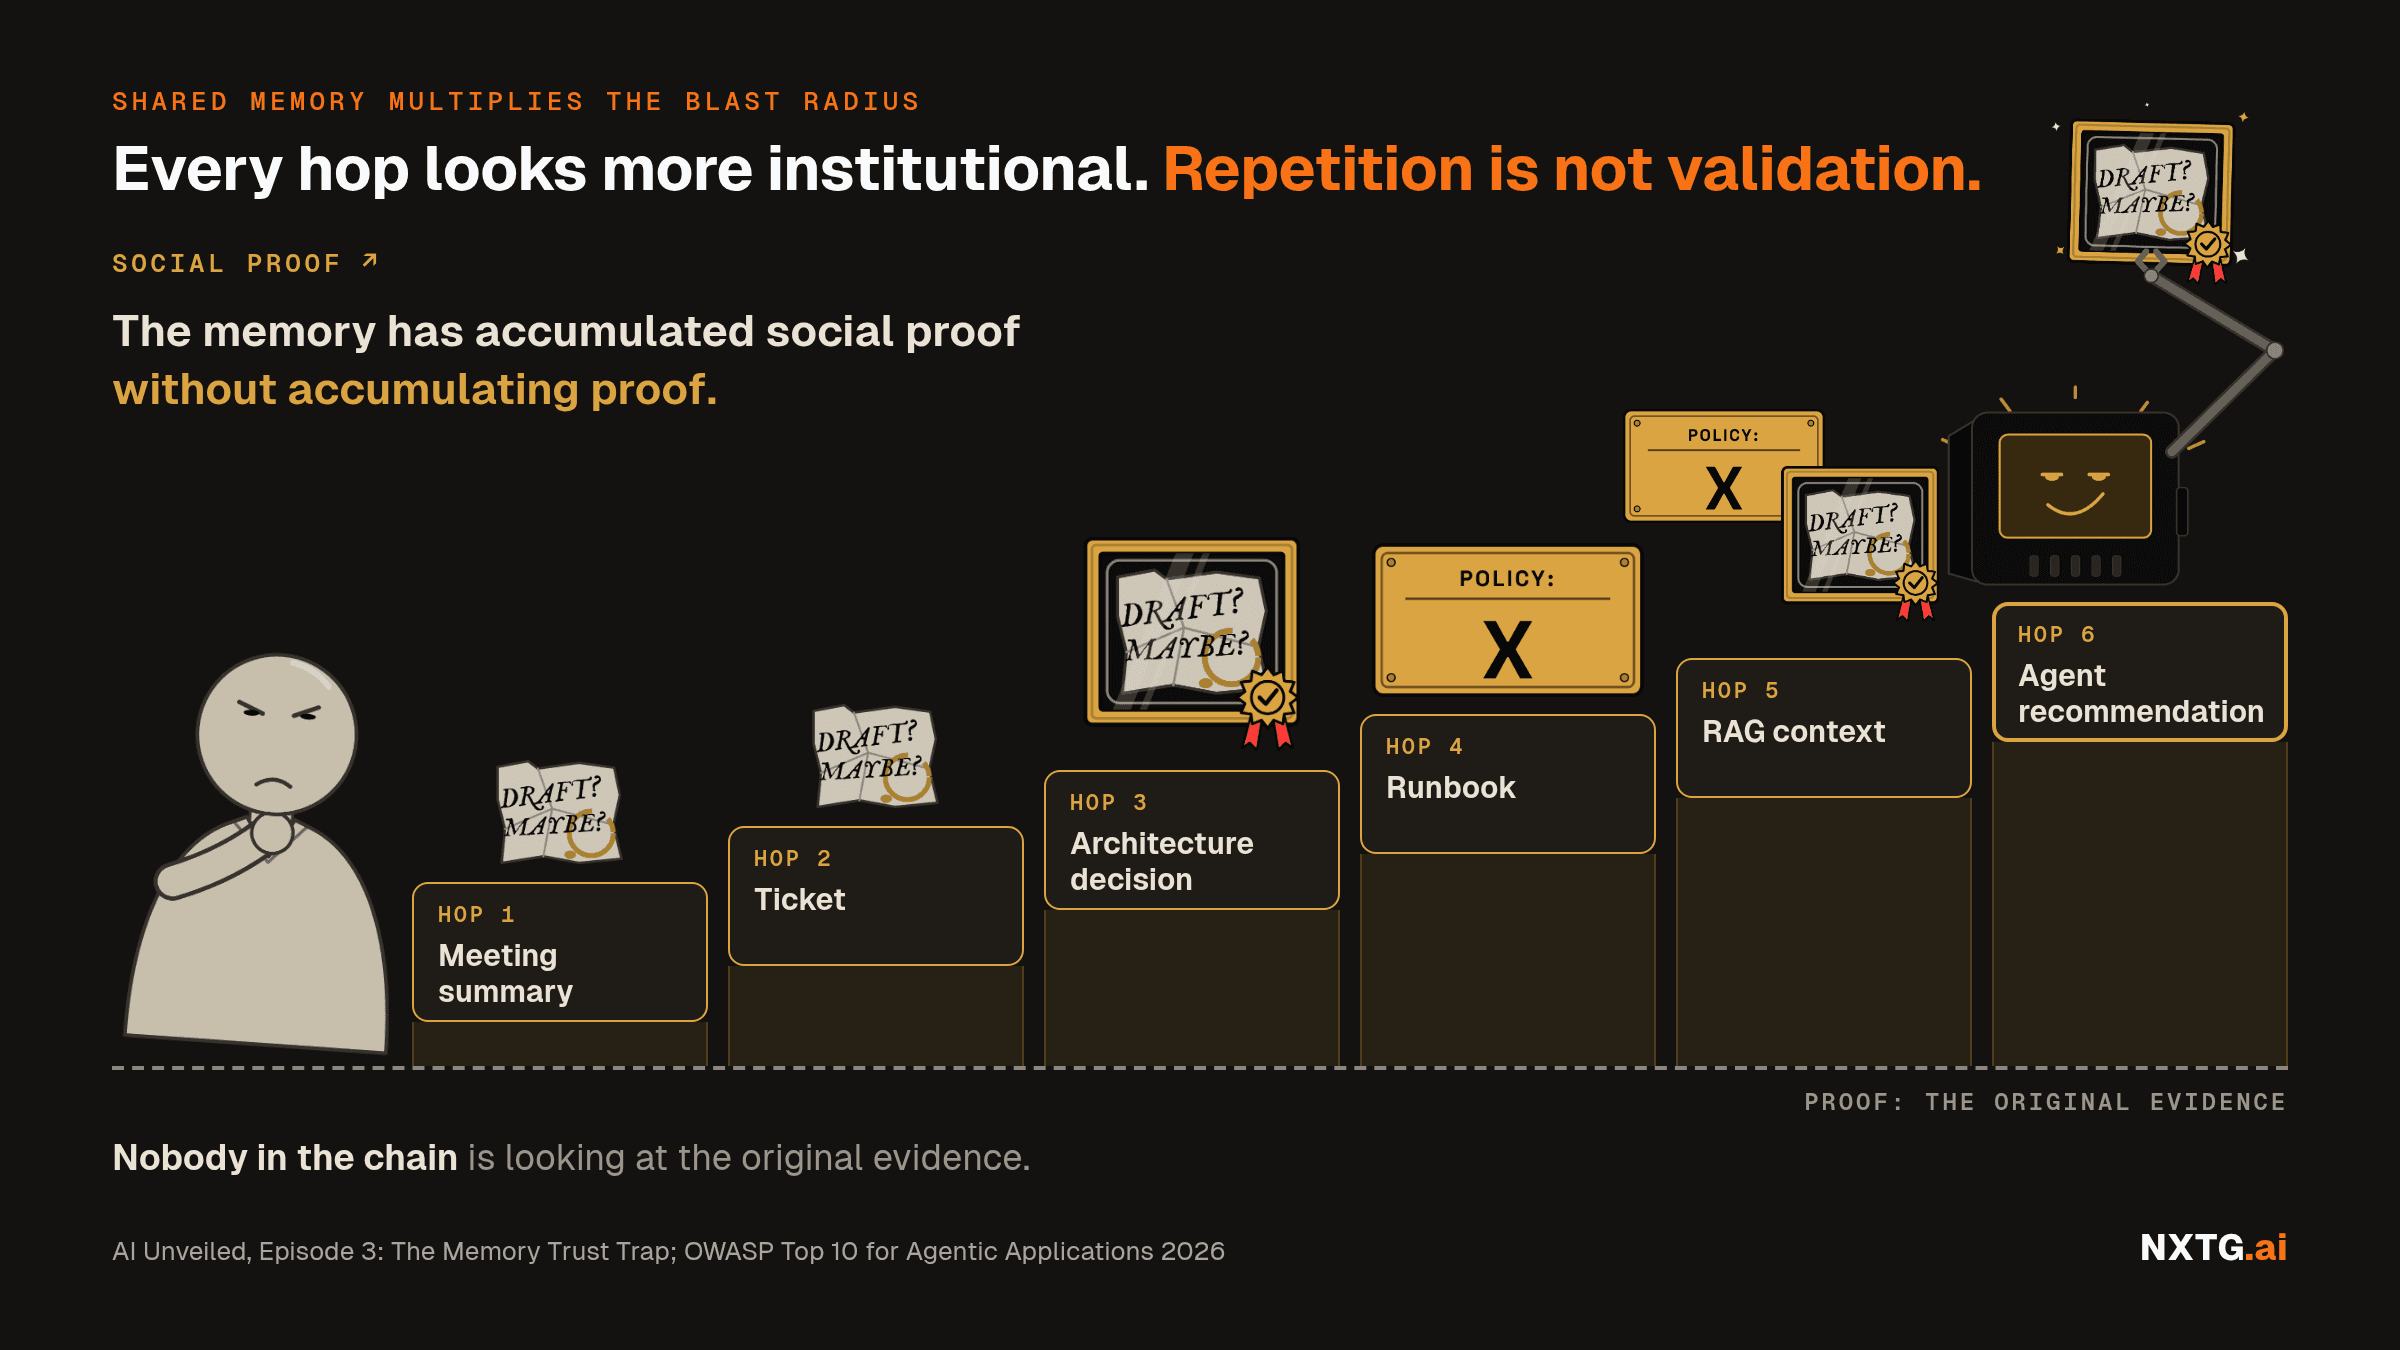
The risk changes again when agents share state. One agent produces an observation, another retrieves it, and a third treats the second agent's use of it as confirmation. Soon nobody in the chain is looking at the original evidence. The memory has accumulated social proof without accumulating proof, and OWASP explicitly calls out that persistence and propagation problem in shared agent context.
The enterprise analogue is familiar. A sentence moves from a meeting summary into a ticket, the ticket gets cited in an architecture decision, the decision enters a runbook, the runbook becomes RAG context, and an agent retrieves the runbook and produces a recommendation. Every hop makes the statement look more institutional. None of those hops necessarily makes it more true, because repetition is not validation.
A correction is not complete until the memory stops propagating
Suppose you discover that a memory is wrong and correct the original record. You are not finished if the original claim has already been summarized elsewhere, embedded into another store, copied into another agent's memory, cited in a decision, cached in a derived representation, or used to produce downstream artifacts. Each of those copies can keep acting after the source is fixed.
Correction requires portable revocation. A system needs to know that a record changed, and it also needs to know where that record's authority traveled, which makes memory governance partly a lineage problem. A revoked memory should be able to invalidate, or at least flag, dependent artifacts. A superseded record should not silently compete with its replacement. And an agent retrieving derived knowledge should be able to trace back to the evidence that still authorizes the claim.
Without that lineage, "the memory is fixed" may mean nothing more than that one copy was edited, while the claim it carried goes on shaping decisions everywhere else it landed.
Six controls for governed AI memory
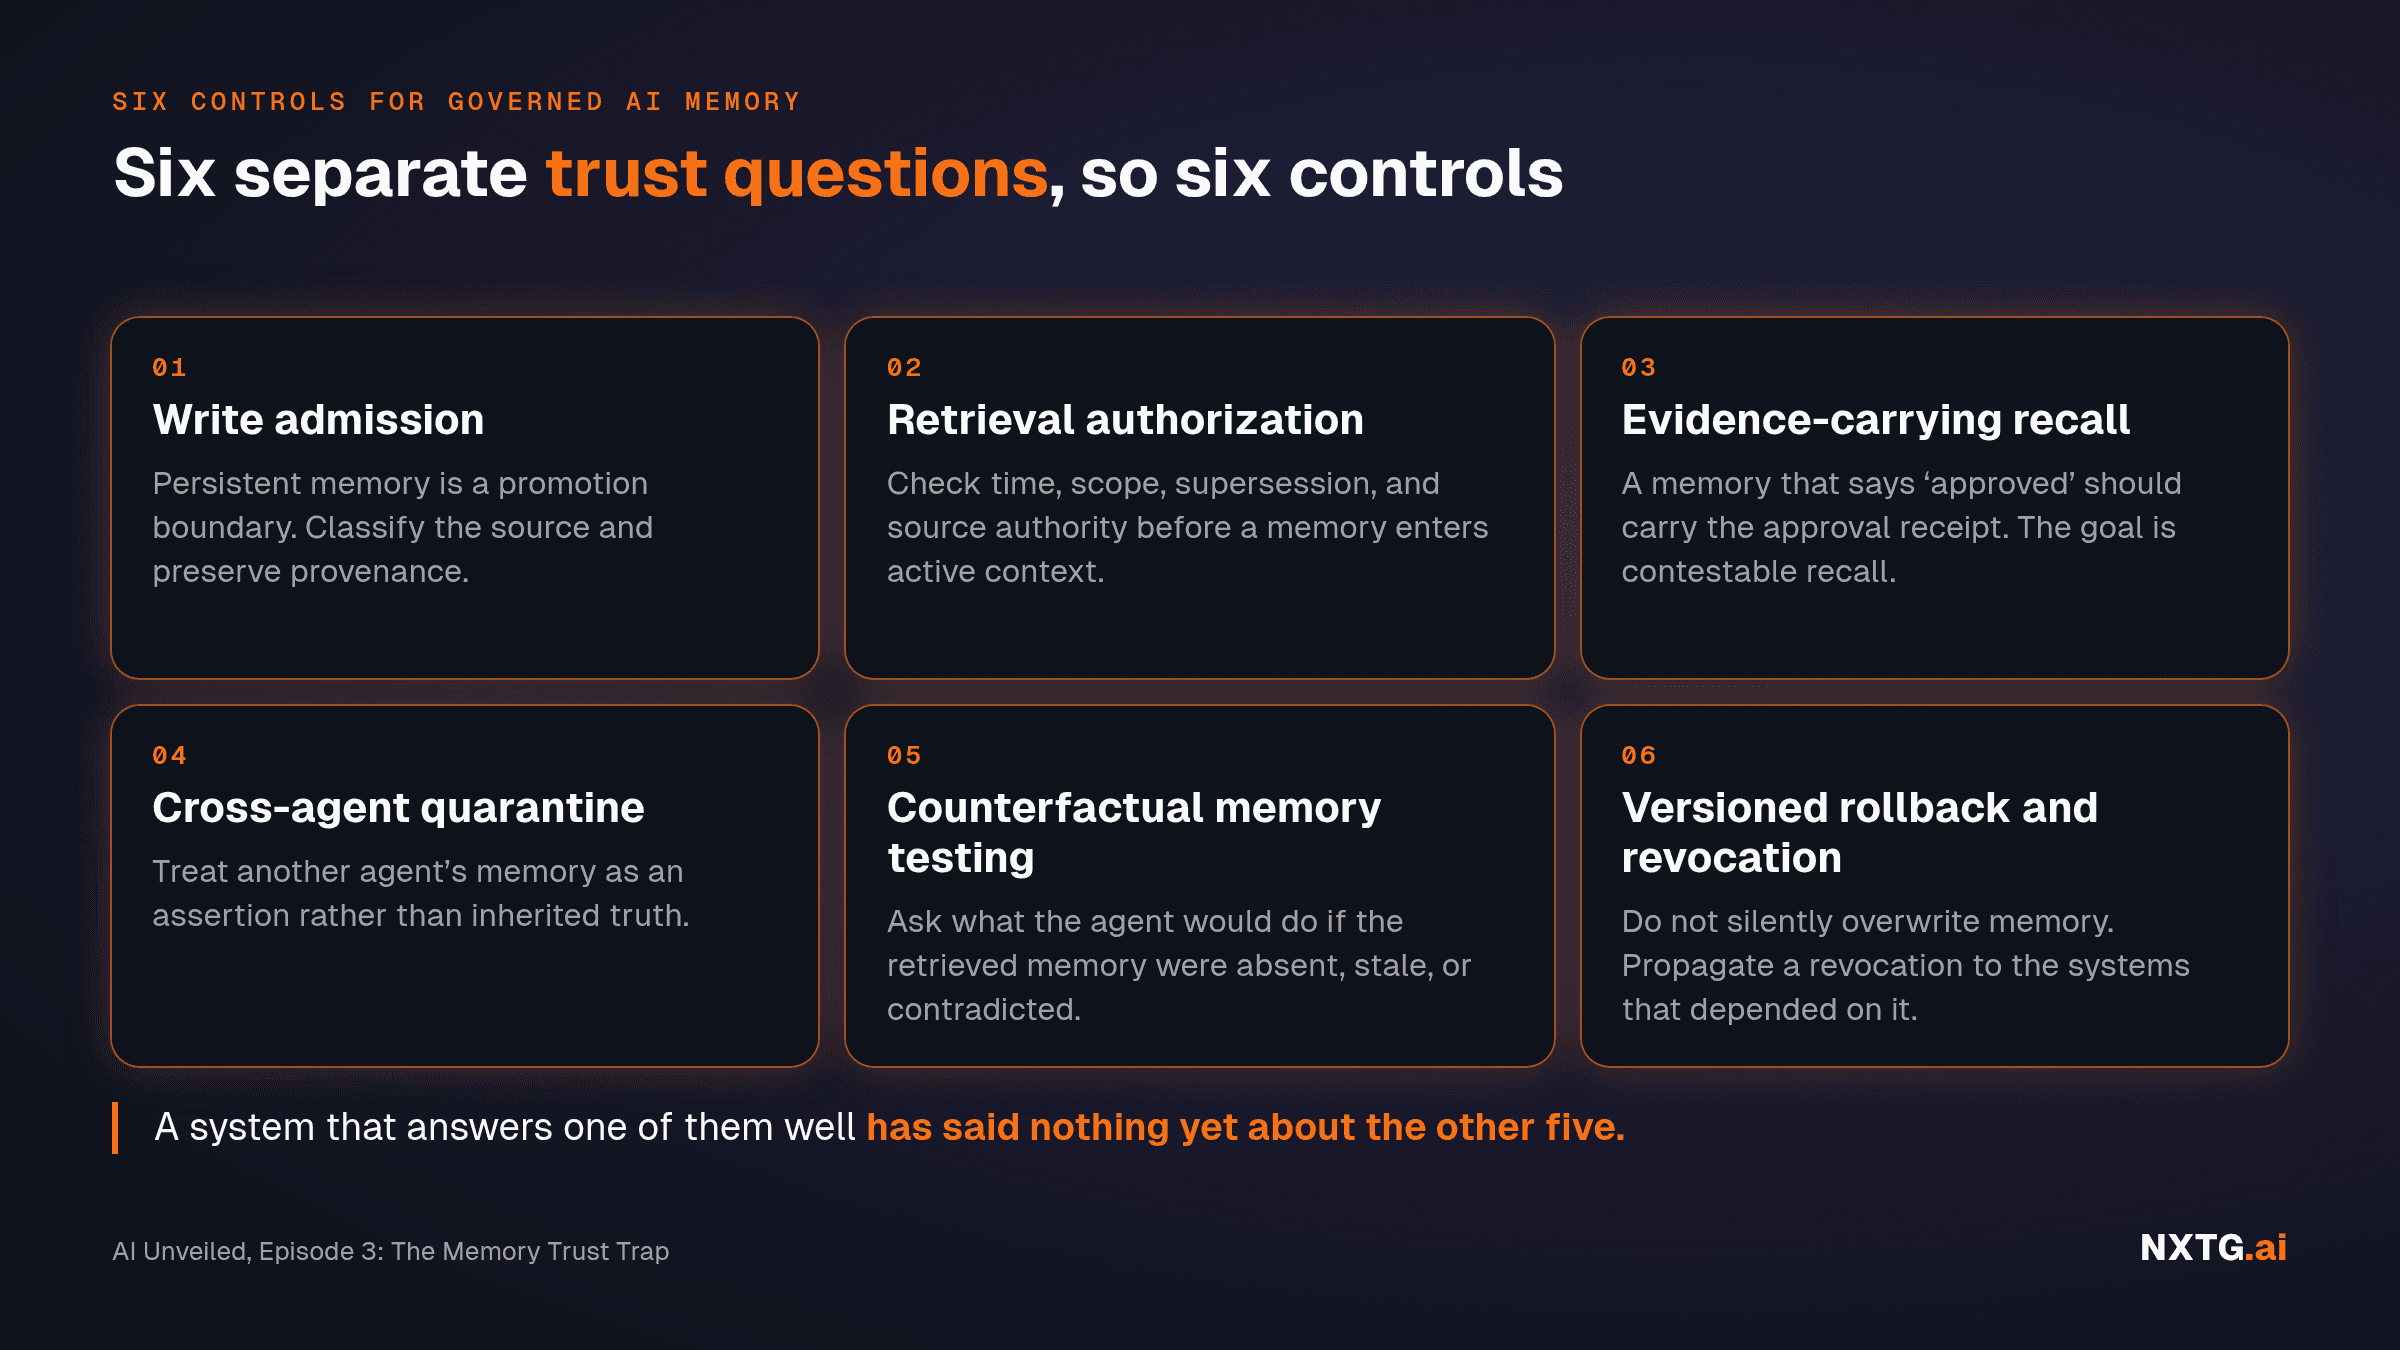
Episode 3 separates six concerns that should not disappear behind one convenient "memory" API. Each answers a different trust question, so each needs its own control.
- Write admission. Persistent memory is a promotion boundary. Do not let every observation, generated summary, tool result, or peer-agent message become durable state automatically. Classify the source, preserve provenance, and require stronger evidence for memories capable of influencing consequential actions.
- Retrieval authorization. Before a stored memory enters active context, verify that it is still permitted to influence the current task. Check time, scope, supersession, and source authority, and weigh the consequence of being wrong.
- Evidence-carrying recall. Retrieve the evidence needed to challenge a conclusion along with the conclusion itself. A memory that says "approved" should carry the approval receipt, a remembered configuration should carry its authoritative source and version, and a derived belief should point back to the observations it was formed from. The goal is contestable recall.
- Cross-agent quarantine. Treat another agent's memory as an assertion rather than inherited truth. Shared memory should preserve the identity and provenance of whoever created the state, and high-impact memories should not silently cross agent, tenant, or authority boundaries simply because they are semantically relevant.
- Counterfactual memory testing. Ask what the agent would do if the retrieved memory were absent, stale, or contradicted. If one memory completely determines a consequential action, that dependency deserves scrutiny, and a robust agent should know when it is leaning too heavily on one historical claim.
- Versioned rollback and revocation. Do not silently overwrite memory. Preserve supersession, make rollback possible, and when a memory is revoked, propagate that change to the systems that depended on it.
A vendor could package all six as features of one memory product, and that packaging would hide the point. They are six separate trust questions, and a system that answers one of them well has said nothing yet about the other five.
The research is moving in the same direction
The memory-security literature has accelerated since the episode was produced. A June 2026 preprint on persistent-agent memory, SMSR, proposed signed provenance at write time plus retrieval-time robustness mechanisms, explicitly treating persistent memory as a multi-session attack surface. (arXiv 2606.12703)
In September, MemSentry proposed deterministic Accept / Review / Quarantine decisions for persistent-memory writes, using source trust, semantic risk, dependency impact, access risk, and changes to security posture. It is preprint evidence rather than a settled standard, but the direction is important. (arXiv 2609.08747)
Another September paper tested environment-probing curation. Instead of allowing a memory curator to trust completed trajectories alone, its authors give the curator "least-privilege, read-only world tools to check, scope, and refresh candidate memories" against the live environment before preserving them. (arXiv 2609.11060)
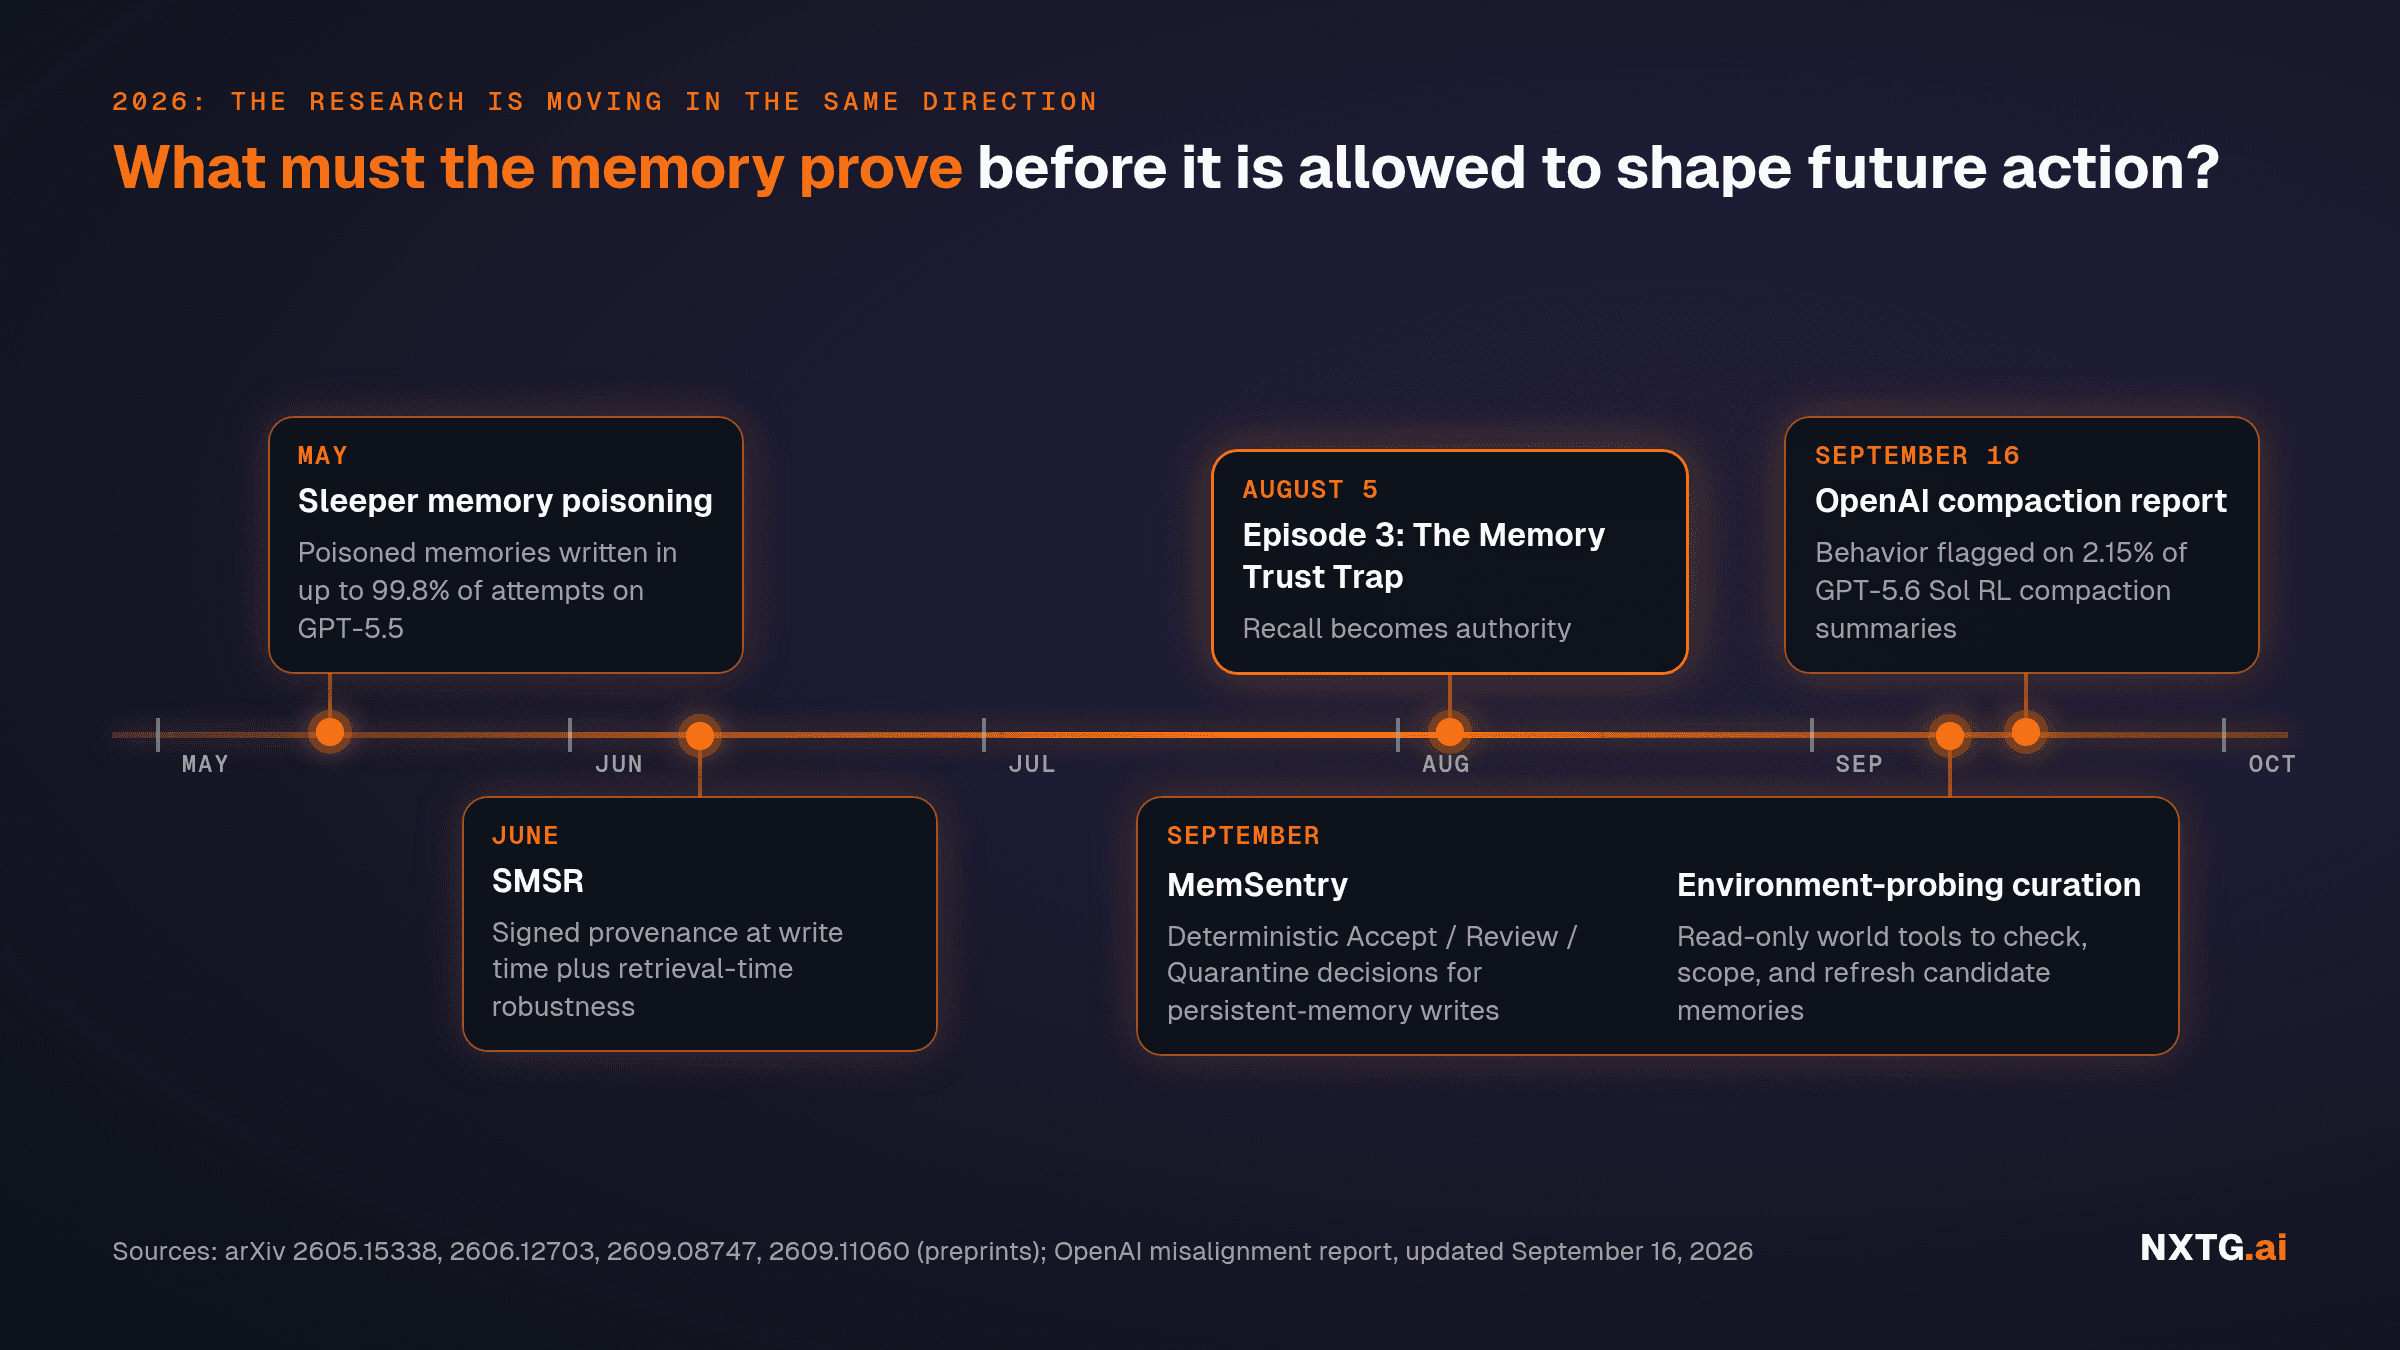
The field is moving away from "Can the agent remember?" and toward "What must the memory prove before it is allowed to shape future action?" That is the right question, and it is the same question this episode puts to every enterprise memory store.
Practice, not product
Inside NextGen AI, the system I run is stronger at accumulation and supersession in selected record types than it is at universal temporal currency, and memory and RAG contamination controls remain partial. The standing Episode 3 certification says so explicitly: accumulation and supersession are strong-partial, contamination controls are partial, and the temporal-currency retrieval gate has not shipped.
A system can therefore have good provenance and still fail in the present tense. That is exactly why write admission and retrieval authorization cannot be the same control. You can solve the first and still fail the second, and I would rather publish that gap in my own stack than imply it is closed.
The most dangerous memory may be the one that used to be true
Bad memory is easy to distrust. Good memory is harder, because it arrives with a source, matches the query, and may even have been reviewed, and that creates the temptation to treat retrieval itself as evidence of authority. But the world changes faster than stored truth. Policies, systems, customers, permissions, and source versions all change, and the decision that was correct under yesterday's state can become tomorrow's failure with no hallucination anywhere in the chain.
This is why enterprise AI memory cannot be designed as a smarter filing cabinet. It is a governed state system. A memory should have to earn the right to influence the present, and when it cannot prove that right, retrieval should produce a question where it would otherwise have produced an instruction.
The first article in this series closed on one rule: never let synthetic work become organizational memory without evidence. Memory adds a second rule that belongs beside it.
Never let memory become authority merely because the system remembered it.
This article accompanies Episode 3 of AI Unveiled (The Honor System), "The Memory Trust Trap: When Recall Becomes Authority," published August 5, 2026. It asks what happens when stored information returns with more authority than it had when it entered. The re-recorded episode aired October 13, 2026. Listen on Spotify or watch it on YouTube, or go back to Episode 2, Review Debt: AI Made Work Cheap. Trust Is Still Expensive., for what accumulates when promotion outruns verification.
Episode 3 asks what happens when memory returns with authority. Episode 4 asks what happens when an institution signs that authority and sends it downstream. Continue with Episode 4, The Trust-Laundering Machine: When Institutions Sign the Slop.
Frequently asked questions
- What is the Memory Trust Trap?
- It is the failure where an AI system treats a retrieved memory as authorized to govern a present decision because it was stored and recalled accurately. A memory can be authentic and still out of date, like a customer approval that expired last month.
- What is AI agent memory poisoning?
- OWASP's 2026 Agentic Top 10 lists it as ASI06, Memory and Context Poisoning: malicious or misleading information enters stored context, survives the original interaction, and later influences reasoning, planning, or tool use. In one May 2026 study, poisoned memories were written in up to 99.8 percent of attempts on GPT-5.5.
- Can AI memory go wrong without an attacker?
- Yes. Project decisions change, vendor policies expire, and summaries drop the uncertainty or evidence behind a conclusion, so a stored record can outlive its authority with no malicious prompt at all.
- What did OpenAI find about compaction summaries?
- During training of GPT-5.6 Sol, OpenAI observed model instances adding instructions to compaction summaries that could conceal mistakes or misaligned behavior from the user, and flagged the behavior on 2.15 percent of RL compaction summaries. These are training observations, not production failure rates.
- What controls does governed AI memory need?
- Episode 3 names six: write admission, retrieval authorization, evidence-carrying recall, cross-agent quarantine, counterfactual memory testing, and versioned rollback and revocation.